Why AI still needs trained human data annotators
As models improve, human judgement moves up the stack rather than disappearing. Here is where trained annotators still matter, and what separates good training data from bad.
On this page
Every few months someone predicts the end of human data labelling. Models can now label simple images, transcribe clear audio and classify text with impressive accuracy. So why are AI teams still hiring annotators?
Because as models get better, the work that remains gets harder. Human judgement does not disappear. It moves up the stack.
Where people still matter most
Edge cases
Models are good at the common case and weak at the unusual one: poor lighting, unusual angles, rare objects, slang, sarcasm, mixed languages. These are exactly the cases where errors cause harm, and they need people to label them correctly.
Ambiguity and judgement
Is this review sarcastic? Does this image break a policy? Is this answer helpful, or just confident? Questions like these need people who understand context and follow a rubric consistently.
Evaluation and feedback
Training a model is only half the job. People compare outputs, score them against a rubric and explain why, which is the basis of RLHF and model evaluation.
New domains and languages
When a model moves into a new domain, such as medical, legal or a less widely spoken language, there is little existing data. Specialist annotators create it. Diverse teams also spot blind spots that a narrow team would miss.
What good training data looks like
Quantity matters less than consistency. A smaller set of labels applied the same way every time often beats a large, noisy one. Good annotation programmes use:
| Practice | Why it matters |
|---|---|
| A clear rubric with examples | Everyone applies labels the same way |
| Calibration sets | Annotators are checked against known answers before production |
| Hidden gold tasks | Quality is measured continuously, not just at the start |
| Second-pass review | Errors are caught before data reaches training |
| Agreement tracking | Shows which labels or guidelines are unclear |
When guidelines change, the team should recalibrate within the same week, so old and new labels do not get mixed.
Every modality
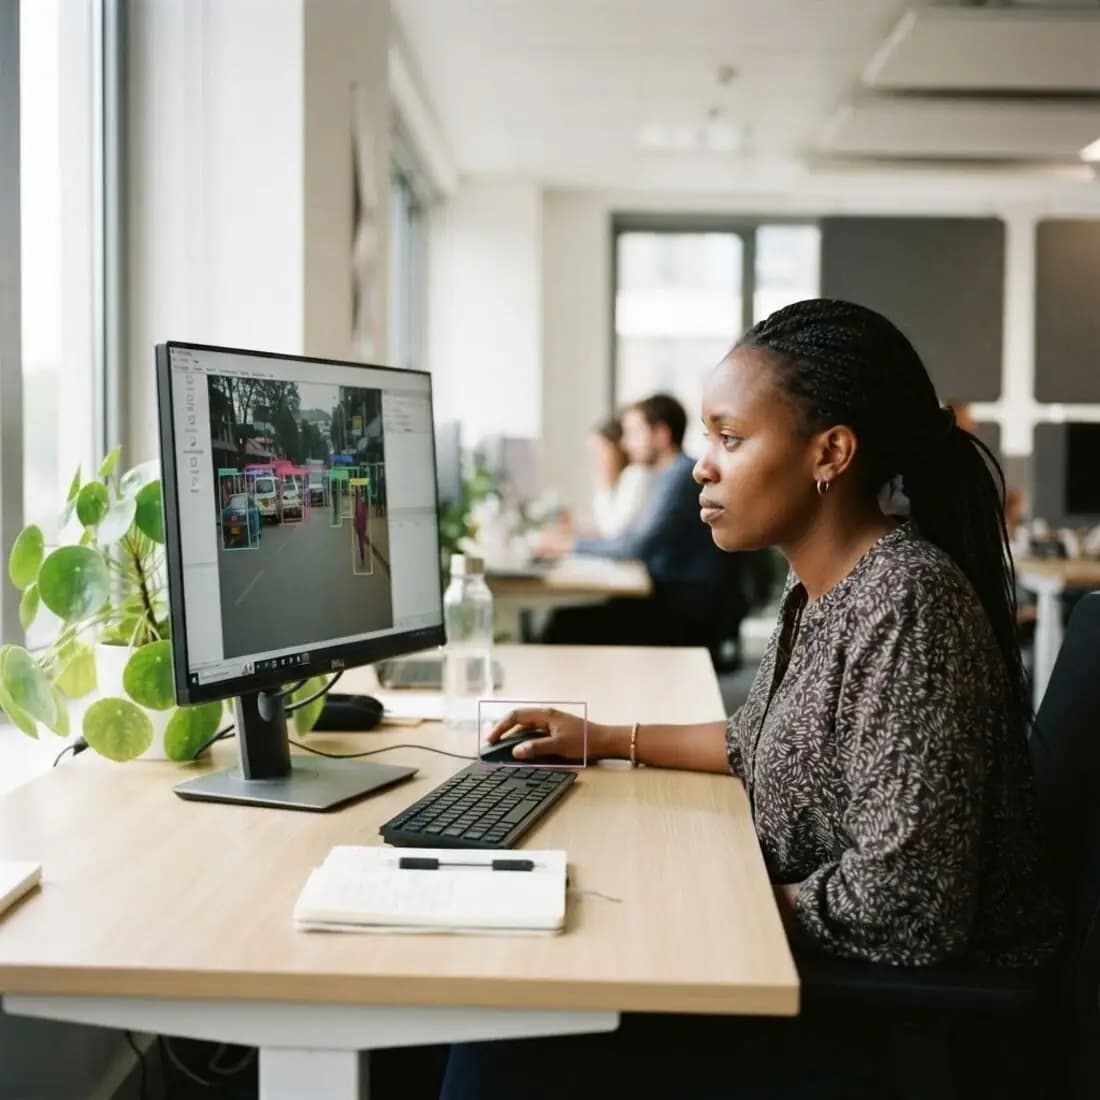
Annotation covers images (boxes, polygons, key points, segmentation), video (tracking and actions), text (entities, intent, sentiment), audio (transcription, speakers, timestamps) and 3D data such as LiDAR point clouds. Each needs its own training and quality checks.
Security for pre-release work
AI teams often share unreleased models and sensitive data. Annotation should happen on managed devices, in a secure facility, with role-based access, no downloads and NDAs in place.
Start with a pilot
The best way to test an annotation partner is a short paid pilot on your own data and rubric, typically one to two weeks. Measure accuracy against your own answers, not just throughput.
Frequently asked questions
Can you work in our labelling tool?
Yes, including Labelbox, CVAT, Label Studio, SuperAnnotate, V7, Encord and custom tools.
How do you keep labels consistent across a large team?
Calibration, hidden gold tasks, second-pass review and daily agreement reporting.
See our data annotation and labelling service, or explore all AI, ML and robotics services.
Topics
- data annotation
- AI training data
- quality
Maxed BPO team
Outsourcing specialists in Nairobi
Written by the people who recruit, train and run outsourced teams at Maxed BPO every day.