Model Evaluation & Safety
Computer Vision QA in Kenya.
Finding where your vision model really fails.
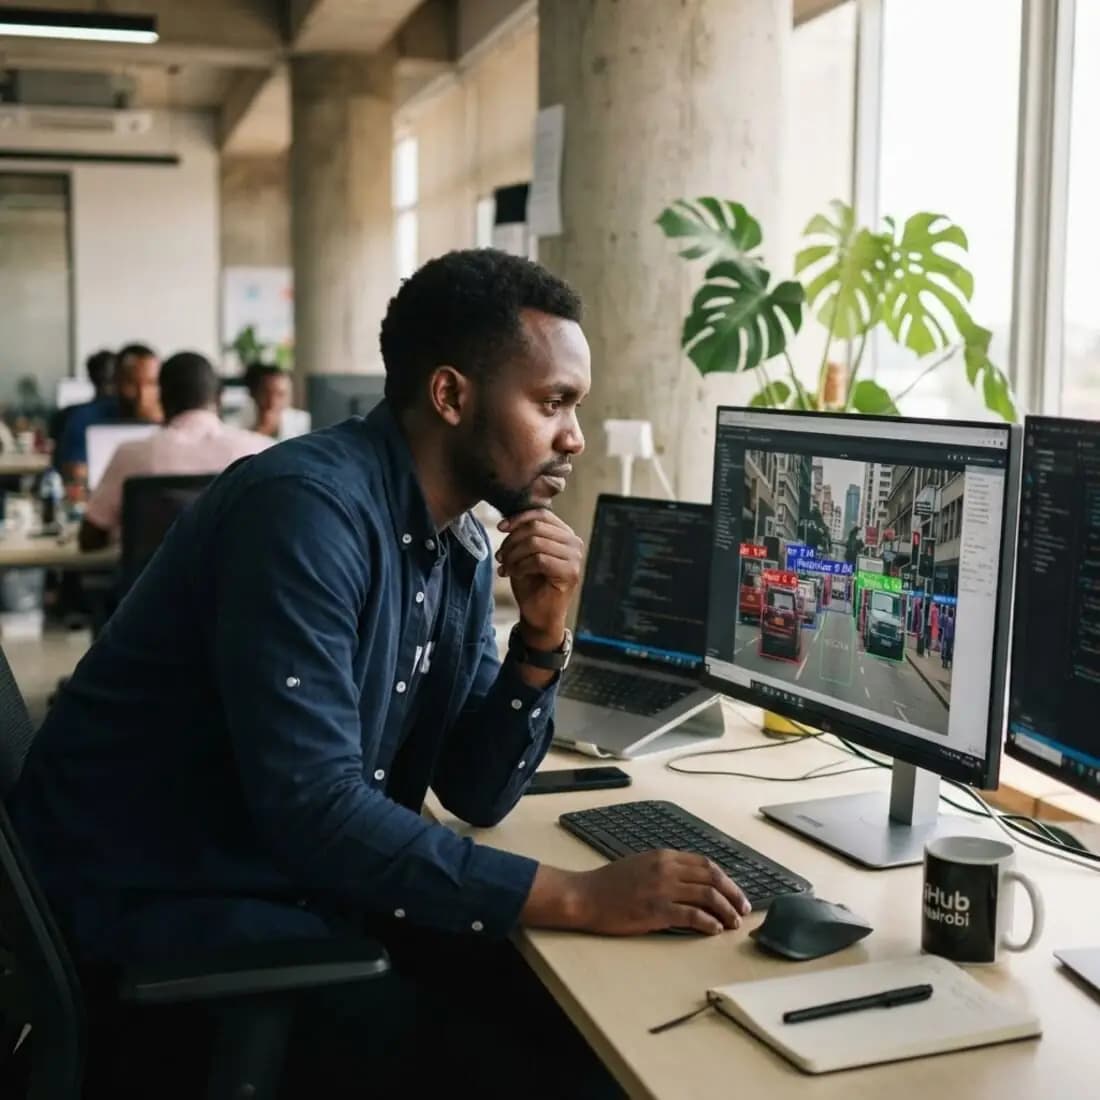
Reviewers who find the failures that strong benchmark scores can hide, and document them so your engineers can fix them.
- Edge-case sets
- Regression checks
- Evidence-backed
100%
Of failures logged with frame and severity
- Detection, segmentation, classification, OCR
- Models
- Acceptance, regression, production sampling
- Checks
- Failure logs, severity, relabels
- Output
- By class, scene and condition
- Reports
Overview
Affordable computer vision QA for companies in Australia, Singapore, the UAE and Nigeria
- 01
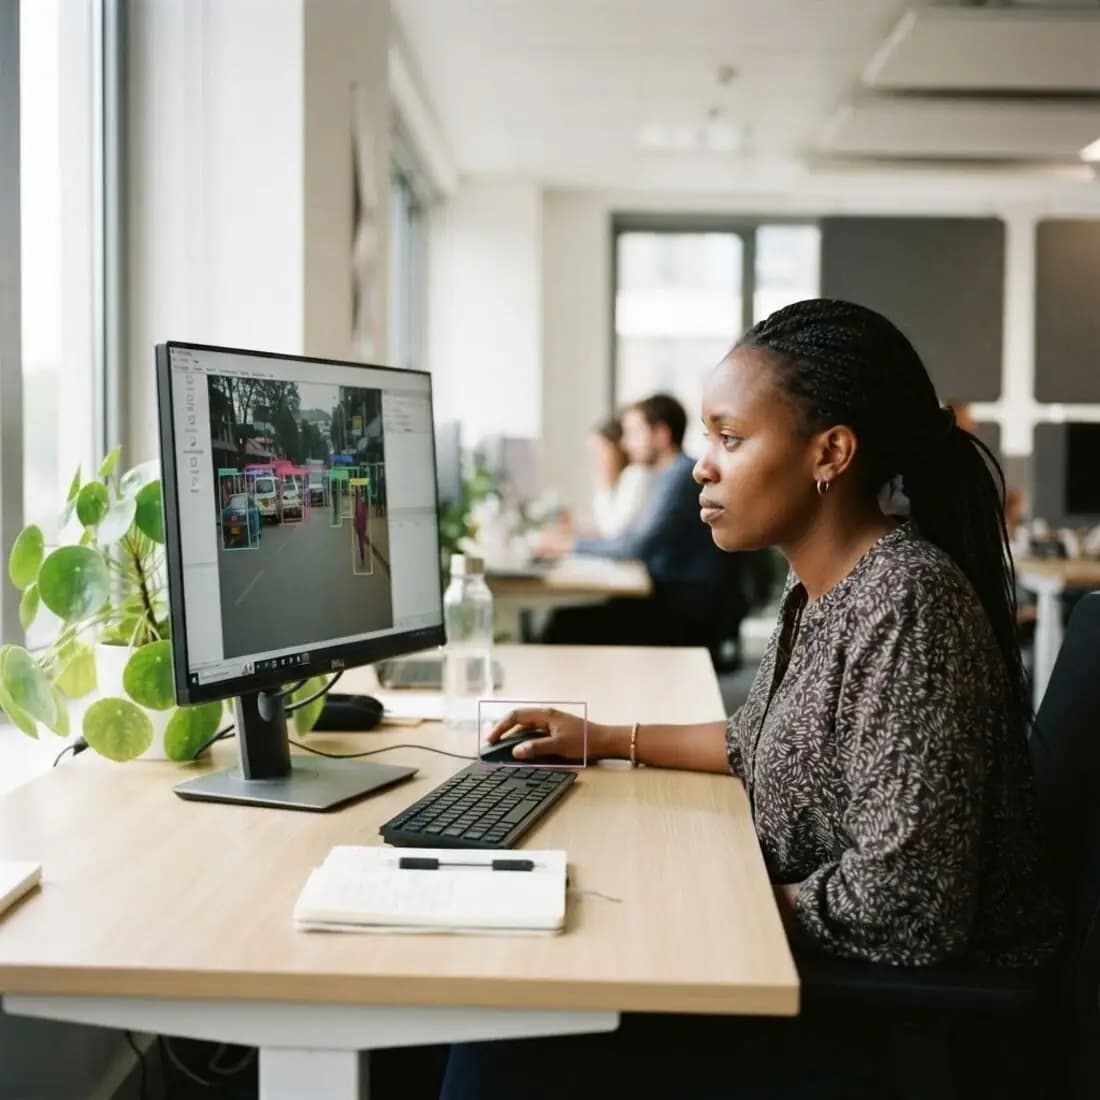
We compare detection, segmentation and classification outputs with ground truth to find false positives, missed objects and boundary errors.
- 02
Evaluation sets are built around hard conditions: poor lighting, rain, motion blur, odd angles, crowds and rare objects.
- 03
Every failure is logged with its frame, the expected and actual result, and a severity rating.
- 04
Reviewers relabel failures on the spot, turning each error into new training data.
- 05
We run acceptance tests on new model versions, regression checks between releases and continuous production sampling.
At a glance
Targets are agreed per client and written into your SLA.
- Of failures logged with frame and severity
- 100%
- Performance breakdown in every report
- Per class
- Regression checked against the last
- Every release
- Production sampling available
- Continuous
What's included
What's included in our computer vision qa service.
Take one piece or all of it. Every item runs to documented procedures with an owner, a target and weekly reporting.
- 01
Prediction audits
Reviewing model outputs against ground truth.
- 02
Edge-case test sets
Curated hard, rare and real-world conditions.
- 03
Release acceptance
Pass or fail checks before a model goes live.
- 04
Regression testing
Making sure new versions do not break what worked.
- 05
Production monitoring
Sampling live output to catch drift.
- 06
Failure relabelling
Turning each error into a corrective training example.
How it fits together
Catch, relabel, retrain.
Model predictions are compared with ground truth, failures are documented and relabelled, and the corrected examples go straight back into training.
How it works
How computer vision qa with Maxed BPO works.
A supervised path from first call to a fully managed team, usually live within 2 to 3 weeks.
- 1
Define success
We agree classes, severity levels and pass thresholds.
- 2
Build test sets
We curate edge cases that reflect your real conditions.
- 3
Audit
Reviewers check predictions and log every failure.
- 4
Report
Structured reports point your engineers at the biggest wins.
Who it's for
Who uses our computer vision qa service.
- Autonomous vehicles and drones
- Retail shelf and checkout vision
- Security and smart camera systems
- Manufacturing defect detection
- Medical imaging and document OCR
Platforms
Tools and platforms we work in.
Your team works inside the systems you already use. Don't see yours? We learn custom tools too.
- CVAT
- FiftyOne
- Labelbox
- Encord
- V7
- Roboflow
- Weights & Biases
- Jupyter
- Python dashboards
- Custom viewers
FAQ
Computer Vision QA: your questions.
Something else on your mind? Our team replies within one working day.
Speak to a specialist
Tell us your volumes and goals. We reply within one working day with a suggested team and price.
Get a free quoteHow is this different from annotation?
Annotation creates labels. QA checks what your model predicts and explains where and why it fails.
Can you build edge-case test sets for us?
Yes, curated around the conditions your product actually faces.
What do reports look like?
Failures broken down by class, scene condition and severity, with example frames.
Can you monitor models in production?
Yes, through ongoing sampling and review of live predictions.
Related AI services
Often paired with computer vision qa.
 Data & Annotation
Data Annotation & Labeling
Accurate training data, labelled by people who follow the rubric.
 Automation & Robotics
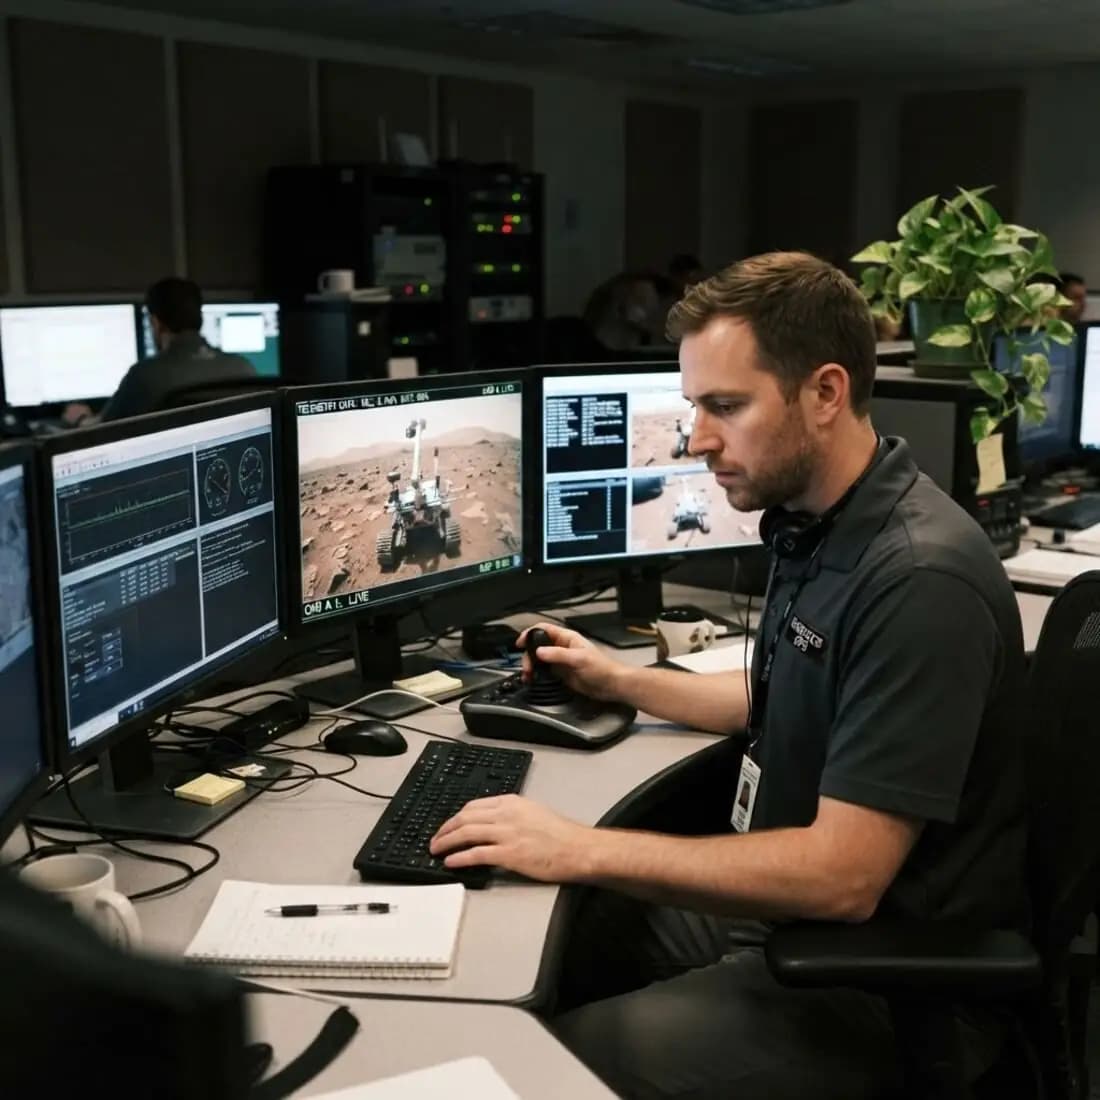
Robotics Remote Operations
Trained remote operators for robots and autonomous fleets.
 Automation & Robotics
Simulation & AR/VR Testing
Real people testing simulated and immersive experiences.
Get a free computer vision QA quote
A no-obligation consultation to design your team, hours and price. Most quotes are back within one working day.