AI, ML & Robotics
The human layer behind trustworthy AI.
Trained human teams for AI, ML and robotics programmes, from labelling training data to auditing model outputs and supporting automation in production. Applied continuously, not only at launch.
- Target label accuracy
- 95%+
- Specialist AI services
- 11
- Minimum review
- 2-pass
- African languages
- 10+
Group 01
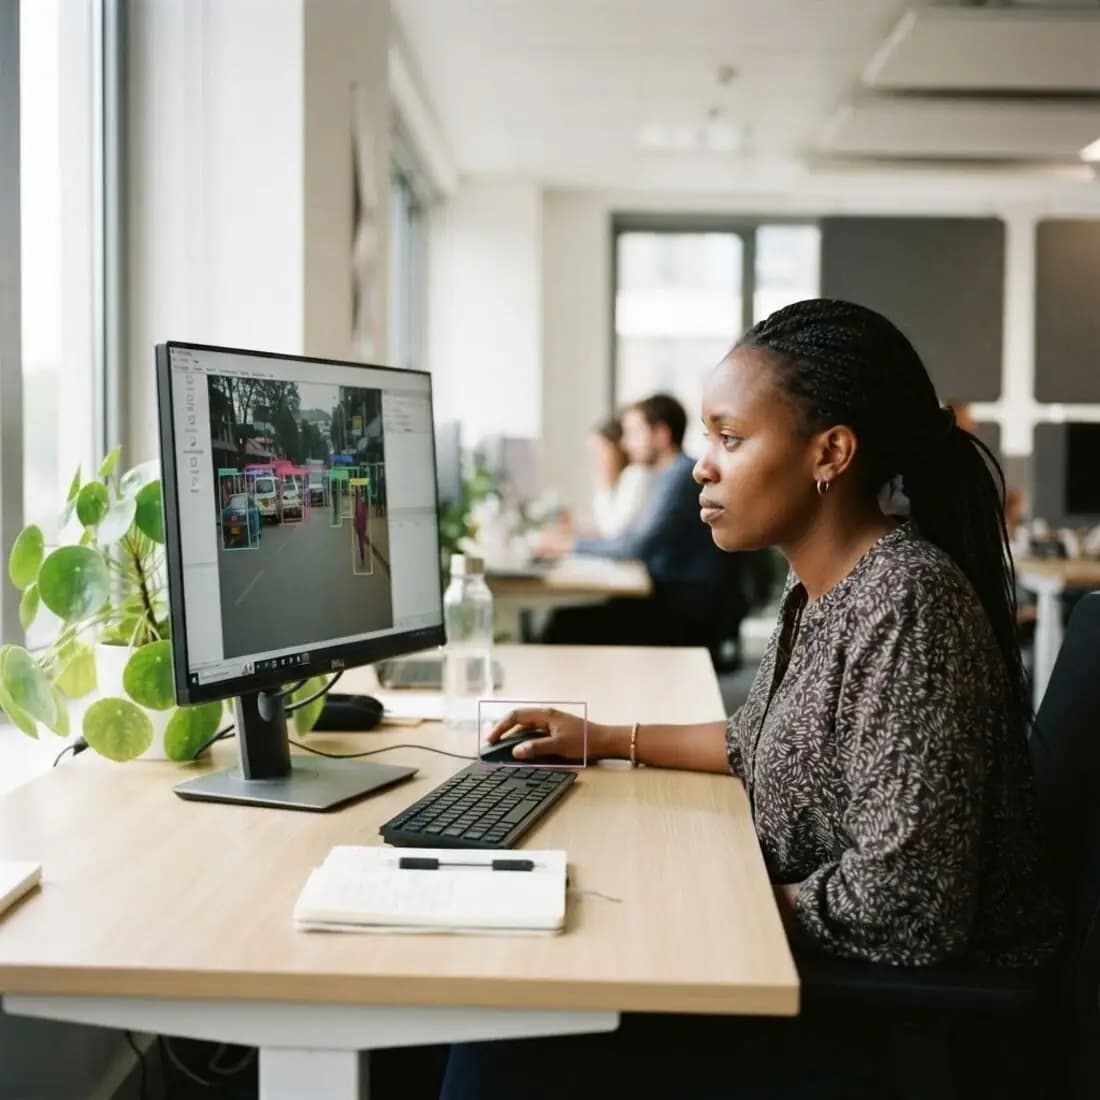
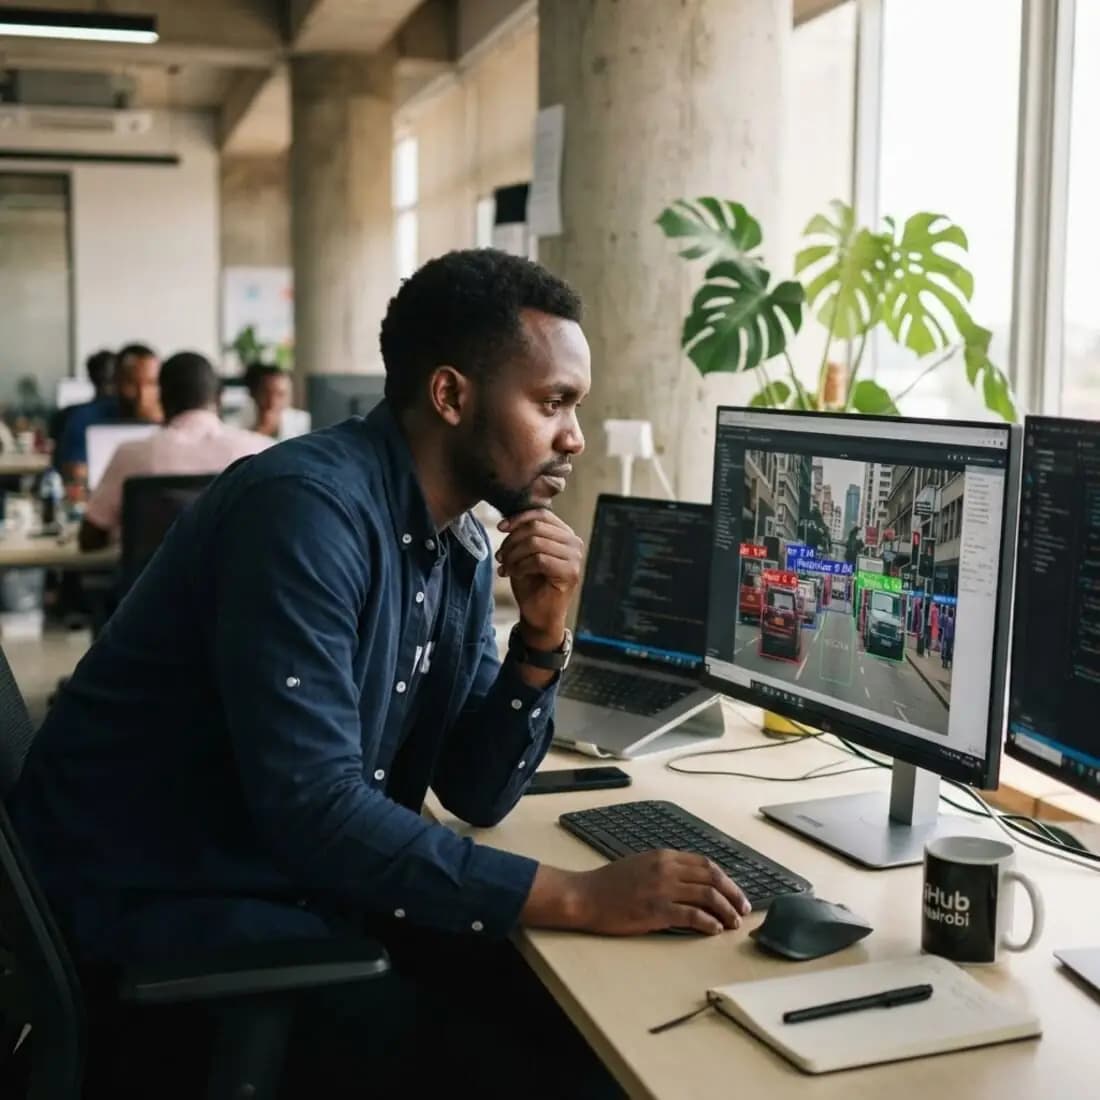
Data & Annotation
Training data labelled, recorded and cleaned to your rubric.
Group 02
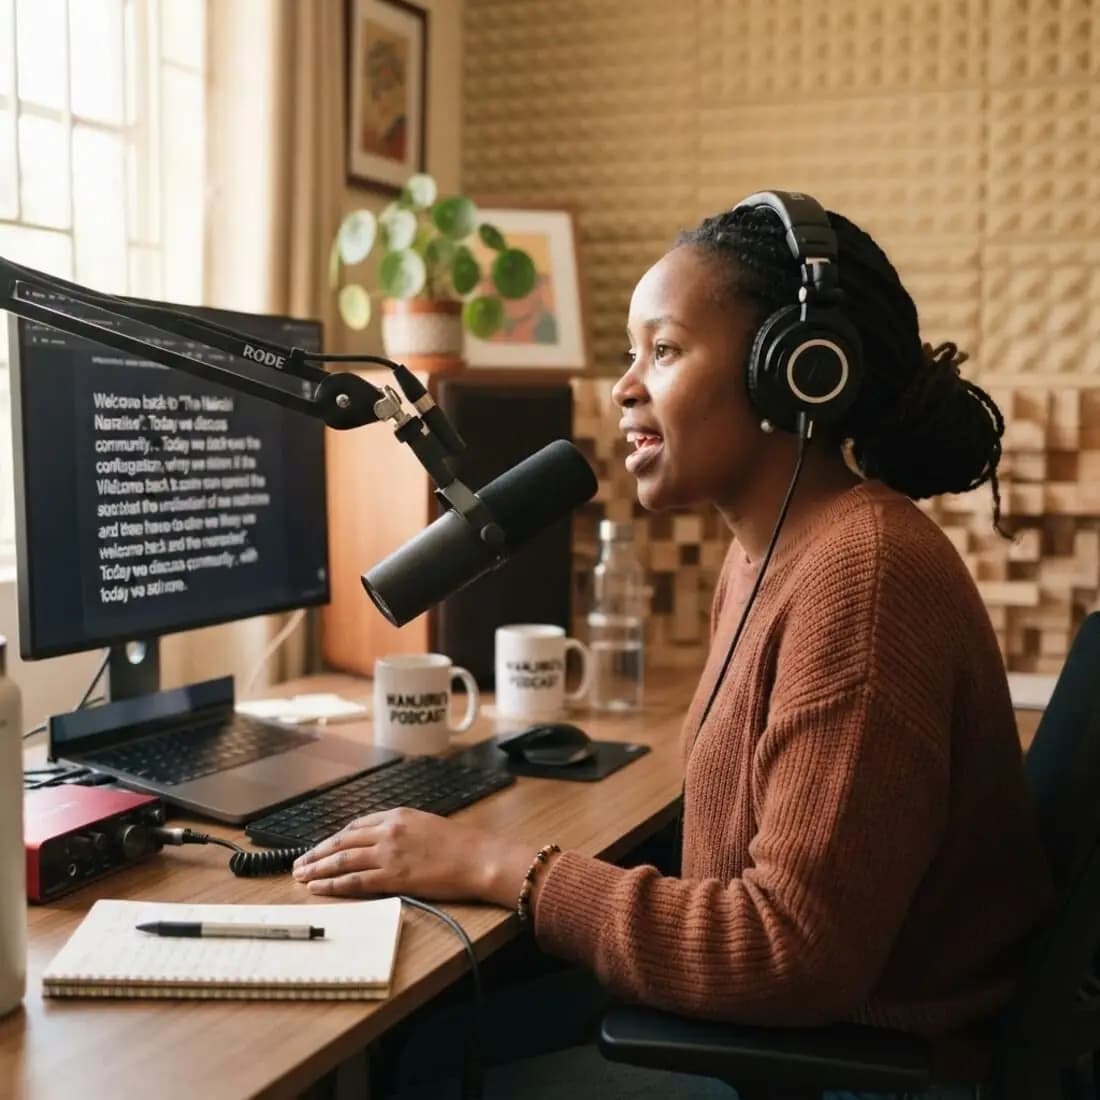
Model Evaluation & Safety
Human judgement that shapes, tests and audits your models.
Group 03
Conversational & Moderation
People behind your chatbot and your community.
Group 04
Automation & Robotics
The human exception team for bots, fleets and simulations.
How it fits together
How raw data becomes training data.
Every project runs the same quality loop, whether you are labelling images, ranking model answers or reviewing robot interventions.
- 01
Raw data
Images, video, text, audio or model outputs arrive in your tool or ours.
- 02
Label
Calibrated annotators apply your rubric.
- 03
Second review
A second annotator checks every batch.
- 04
Gold check
Hidden gold tasks measure accuracy and agreement.
- 05
Training pipeline
Clean, consistent data delivered on schedule.
Errors feed back into the rubric. Disagreements and failed gold tasks trigger same-week calibration, so quality improves batch after batch instead of drifting.
Why this work exists
Why AI still needs trained humans.
“As models improve, the need for human judgement does not disappear. It moves higher up the stack.”
From labelling raw data to ranking subtle model answers and auditing for bias, the work gets harder, not easier. That is where a calibrated, well-managed team makes the difference.
Quality at scale
- Calibration before production
- Hidden gold-standard tasks
- Second-pass review
- Daily agreement reporting
Confidential by design
- Managed devices in a secure facility
- Role-based access and full logging
- No downloads or personal devices
- An NDA for every team member
Specialist pools
- Computer science and maths
- Healthcare and medical imagery
- Law and legal documents
- Swahili and other African languages
We work in your annotation, evaluation and operations tools
- Labelbox
- CVAT
- Label Studio
- Scale
- SuperAnnotate
- V7
- Encord
- Prodigy
- SageMaker Ground Truth
- FiftyOne
- Argilla
- Foxglove
- UiPath
- Custom tools
FAQ
AI services: your questions.
Something else on your mind? Our team replies within one working day.
Speak to a specialist
Tell us your volumes and goals. We reply within one working day with a suggested team and price.
Get a free quoteHow much does data annotation cost?
Priced per hour or per task. After a sample we send a written quote within one working day.
How quickly can you start?
A pilot can run within a few days of receiving your guidelines, and full teams are usually live in 2 to 3 weeks.
How do you keep quality high at scale?
Calibration before production, hidden gold-standard tasks, second-pass review and daily agreement reporting.
Which platforms do you work in?
Labelbox, CVAT, Label Studio, Scale, SuperAnnotate, V7, Encord and custom tools.
Do you have specialist annotators?
Yes, pools with backgrounds in computer science, maths, healthcare, law and African languages.
How do you keep our data and models confidential?
Managed devices, a secure facility, role-based access, full logging and an NDA for every team member.
Hire AI trainers and data annotators from Kenya.
Start with a short paid pilot. We send a suggested team, rubric plan and price within one working day.