Model Evaluation & Safety
AI Model Evaluation & RLHF in Kenya.
Careful human judgement for model training and evaluation.
Trained, calibrated evaluators whose comparative judgements are consistent enough to train reinforcement learning from human feedback.
- Human preference data
- Rubric-calibrated
- Fast feedback loops
100%
Of judgements come with a written rationale
- Ranking, rating, rewriting, prompt writing
- Tasks
- General, code, reasoning, creative, safety
- Domains
- Scores plus a written rationale
- Output
- Calibration and agreement tracking
- Quality
Overview
Affordable AI model evaluation and RLHF for companies in the UK, Ireland, the Netherlands and Singapore
- 01
Evaluators rank outputs, write preference comparisons and score responses against your rubric for helpfulness, accuracy, tone, instruction-following and safety.
- 02
Every judgement comes with a short written rationale explaining why one answer beat another.
- 03
Evaluators are calibrated against reference examples before they start, then checked against hidden reference items and senior reviewers.
- 04
Anyone who drifts is re-calibrated quickly, so your reward signal stays clean.
- 05
Pools are built by domain: general, coding, maths and reasoning, creative writing, dialogue and safety-sensitive content.
At a glance
Targets are agreed per client and written into your SLA.
- Of judgements come with a written rationale
- 100%
- Re-calibration against reference items
- Weekly
- Evaluation shifts available
- 24/7
- To stand up a pilot pool
- Days
What's included
What's included in our model evaluation & rlhf service.
Take one piece or all of it. Every item runs to documented procedures with an owner, a target and weekly reporting.
- 01
Preference ranking
Comparing responses and choosing the better one, with reasons.
- 02
Rubric scoring
Rating responses on your dimensions, such as accuracy, tone and safety.
- 03
Multi-turn evaluation
Judging whole conversations, not single replies.
- 04
Response rewriting
Writing ideal answers for supervised fine-tuning datasets.
- 05
Prompt creation
Diverse, realistic prompts that test real-world use.
- 06
Side-by-side testing
Comparing model versions before release decisions.
How it fits together
Where human feedback fits.
Your model generates responses, trained evaluators compare and score them, and those judgements become the reward signal that shapes the next model version.
How it works
How model evaluation & rlhf with Maxed BPO works.
A supervised path from first call to a fully managed team, usually live within 2 to 3 weeks.
- 1
Rubric review
We study your guidelines and flag ambiguities before work begins.
- 2
Calibration
Evaluators score reference items until agreement targets are met.
- 3
Production
Daily evaluation with hidden checks and senior review.
- 4
Insight
Reports on common failure types to guide your next training run.
Who it's for
Who uses our model evaluation & rlhf service.
- Large language model developers
- AI product teams fine-tuning their own models
- Conversational AI and chatbot companies
- Research labs running human evaluations
- Enterprises testing AI before rollout
Platforms
Tools and platforms we work in.
Your team works inside the systems you already use. Don't see yours? We learn custom tools too.
- Your evaluation platform
- Label Studio
- Argilla
- Scale
- Google Sheets
- Airtable
- Custom web apps
- Slack
- Jira
FAQ
Model Evaluation & RLHF: your questions.
Something else on your mind? Our team replies within one working day.
Speak to a specialist
Tell us your volumes and goals. We reply within one working day with a suggested team and price.
Get a free quoteHow do evaluators agree with each other?
Calibration before production, hidden reference items during work, and re-calibration whenever the rubric changes.
Can you evaluate code and maths?
Yes, with specialist pools holding computer science, engineering and mathematics degrees.
Do evaluators see sensitive content?
Only where the project requires it, with consent, exposure limits and wellbeing support.
How fast can you start?
A pilot pool can usually be ready within a few days of receiving your guidelines.
Related AI services
Often paired with model evaluation & rlhf.
 Model Evaluation & Safety
AI Safety & Bias Auditing
Evidence-based safety and bias testing for AI models.
 Data & Annotation
Data Annotation & Labeling
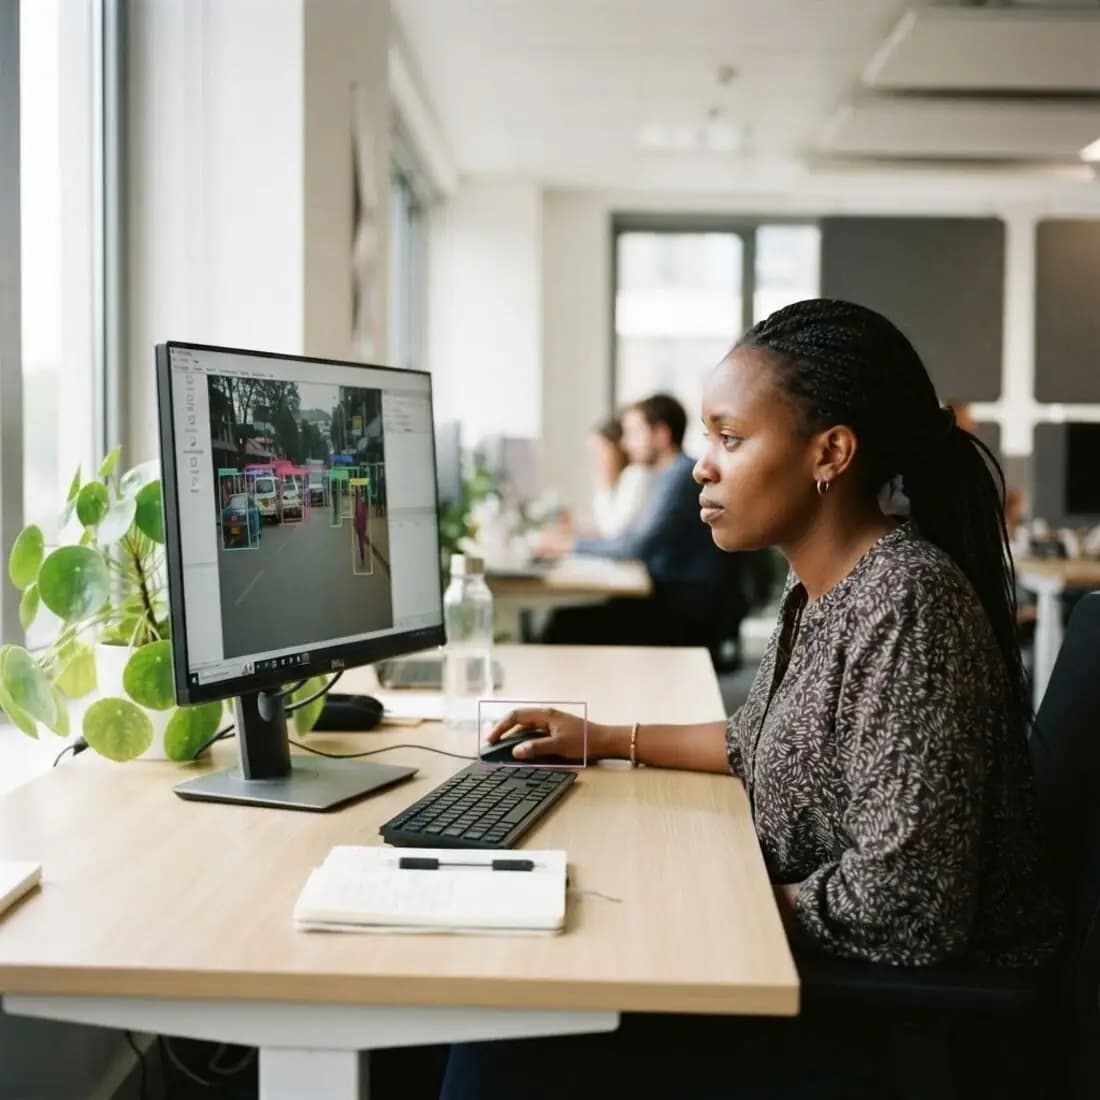
Accurate training data, labelled by people who follow the rubric.
 Conversational & Moderation
Content Moderation
Content moderation with judgement, consistency and care.
Get a free model evaluation and RLHF quote
A no-obligation consultation to design your team, hours and price. Most quotes are back within one working day.