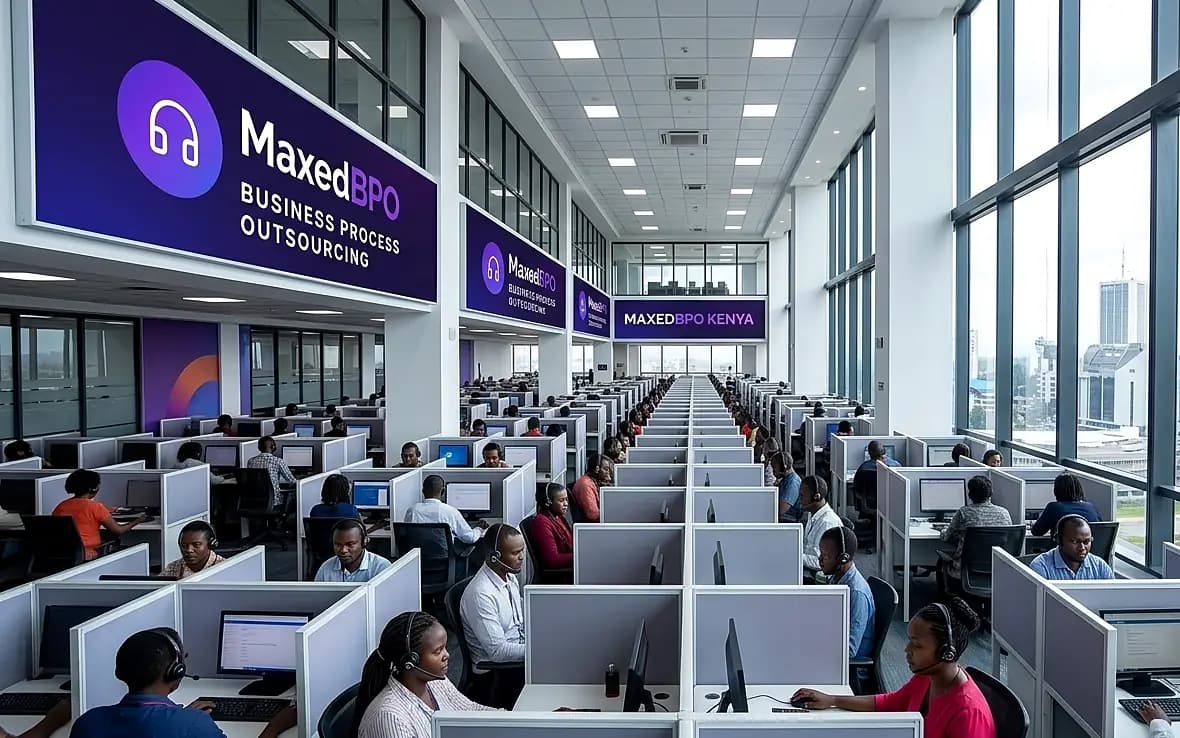
Nairobi delivery centre, serving clients on five continents

+254 140 403 425[email protected]Staff sign in
MaxedBPOBusiness Process Outsourcing
  • Blog
  • Contact
Sign inGet a quote
MaxedBPOBusiness Process Outsourcing

Dedicated offshore teams for customer service, call center, back-office and AI data work, delivered from Nairobi to clients worldwide since 2015.

  • Malik Heights, Ngong Road, Nairobi, Kenya
  • +254 140 403 425
  • [email protected]
  • Chat on WhatsApp

Solutions

  • Customer Service
  • Call Center
  • Back-Office Operations
  • Technical Support
  • Sales & Lead Generation
  • Live Chat & Email
  • Dedicated Teams
  • Virtual Assistants
  • Quality & Compliance
  • Debt Collection

AI, ML & Robotics

  • Data Annotation & Labeling
  • Voice & Speech Data
  • Data Cleaning & Preparation
  • Model Evaluation & RLHF
  • Computer Vision QA
  • AI Safety & Bias Auditing
  • Content Moderation
  • All AI services

Industries

  • Travel & Hospitality
  • Telecommunications
  • Banking & Insurance
  • E-commerce & Retail
  • Healthcare
  • Logistics & Courier
  • IT & Technology
  • Real Estate
  • Education & EdTech
  • All industries

Company

  • About Maxed BPO
  • Our History
  • Leadership Team
  • Success Stories
  • Community Work
  • Careers
  • Blog
  • Contact

Outsourcing to Kenya

  • For United States
  • For Canada
  • For United Kingdom
  • For Europe
  • For Middle East
  • For Africa
  • For Australia
  • For Asia-Pacific
  • Kenya vs Philippines
  • All countries we serve

© 2026 Maxed BPO. All rights reserved.

Privacy PolicyTermsFAQ

Nairobi delivery centre, serving clients on five continents

+254 140 403 425[email protected]Staff sign in
MaxedBPOBusiness Process Outsourcing
  • Blog
  • Contact
Sign inGet a quote
  1. Home
  2. /Blog
  3. /AI and data
  4. /RLHF explained: how human feedback trains AI models
AI and data

RLHF explained: how human feedback trains AI models

A clear explanation of reinforcement learning from human feedback, what evaluators actually do, how consistency is maintained and how to run an evaluation programme.
MBMaxed BPO teamOutsourcing specialists in Nairobi11 August 2026·3 min read
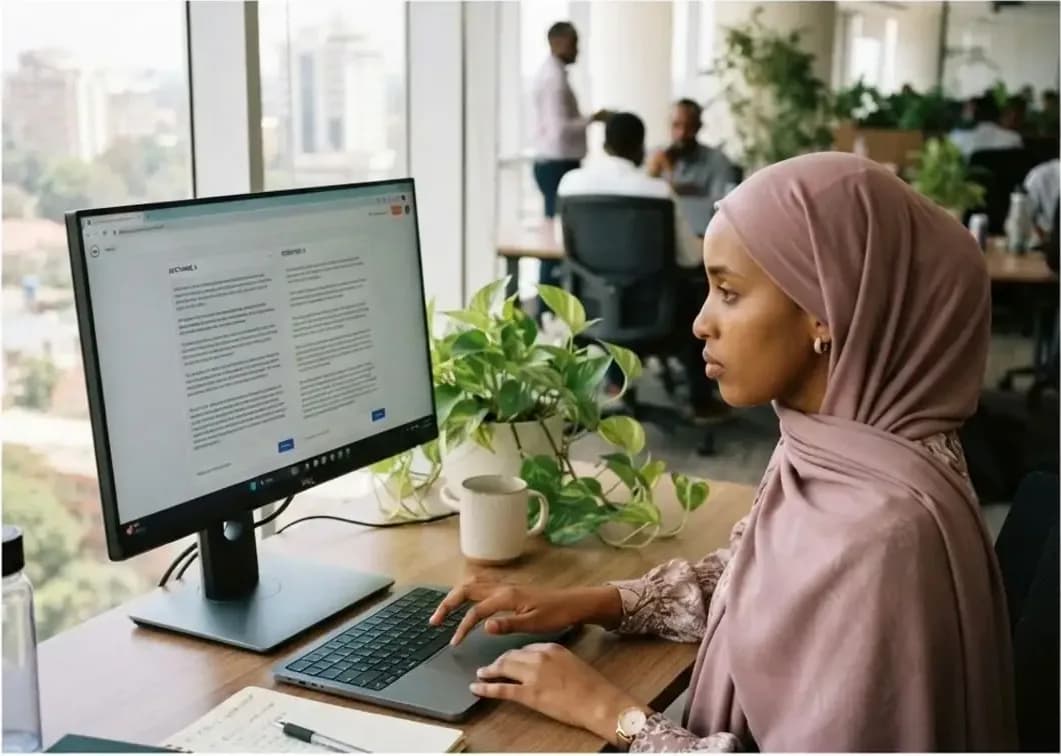
An evaluator comparing two AI model responses on screen

On this page

  1. The idea in one paragraph
  2. What evaluators actually do
  3. Why rationales matter
  4. Consistency is everything
  5. Specialist pools
  6. Wellbeing
  7. Running a programme
  8. Frequently asked questions

Share this post

On this page
  1. The idea in one paragraph
  2. What evaluators actually do
  3. Why rationales matter
  4. Consistency is everything
  5. Specialist pools
  6. Wellbeing
  7. Running a programme
  8. Frequently asked questions

Large language models learn a great deal from text, but text alone does not teach them which answers people find helpful, accurate and safe. That is where reinforcement learning from human feedback, or RLHF, comes in.

The idea in one paragraph

A model produces several responses to the same prompt. Trained evaluators compare them and say which is better, often with scores against a rubric and a written reason. Those judgements become the signal used to adjust the model, so it produces more of what people prefer and less of what they do not.

What evaluators actually do

  • Preference ranking: choose the better of two or more responses.
  • Rubric scoring: rate responses on helpfulness, accuracy, tone, instruction following and safety.
  • Rewriting: improve a weak response to show what a good one looks like, which is useful for supervised fine-tuning data.
  • Prompt writing: create realistic and challenging prompts.
  • Multi-turn evaluation: judge whole conversations, not just single replies.
  • Side-by-side testing: compare a new model release against the previous one.

Why rationales matter

A score alone is hard to audit. A short written reason for every judgement explains what the evaluator saw, makes disagreements easy to investigate and gives model teams insight into failure patterns.

Consistency is everything

If two evaluators judge the same response differently, the model learns noise. Good programmes keep evaluators consistent through:

  1. 1Calibration on reference examples before production work starts;
  2. 2hidden reference items mixed into the queue to measure drift;
  3. 3senior review of a sample of judgements;
  4. 4re-calibration whenever the rubric changes, and regularly anyway.

Evaluators who drift are re-calibrated before they continue.

Specialist pools

General evaluation suits many tasks, but some need expertise: code, mathematics and reasoning, creative writing, dialogue and safety. Specialist pools with relevant degrees or experience produce more reliable judgements in these areas.

Wellbeing

Safety evaluation can involve disturbing content. Evaluators should only see it with consent, with exposure limits, rotation and wellbeing support in place.

Running a programme

  1. 1Rubric review: agree definitions and examples.
  2. 2Calibration: test the pool against your reference answers.
  3. 3Production: daily output with quality and agreement reporting.
  4. 4Insight: share patterns in model failures with your team.

A pilot pool can usually be stood up within days.

Frequently asked questions

How do you measure evaluator agreement?

With hidden reference items, agreement tracking and re-calibration whenever the rubric changes.

Can you evaluate code and maths?

Yes, with specialist pools who have computer science, engineering or mathematics backgrounds.

Learn more about our AI model evaluation and RLHF service.

Topics

  • RLHF
  • model evaluation
  • LLMs

Share this post

MB

Maxed BPO team

Outsourcing specialists in Nairobi

Written by the people who recruit, train and run outsourced teams at Maxed BPO every day.
All posts

Keep reading

  • A speaker recording audio in a quiet boothAI and data

    Speech data for African languages and accents: why it matters and how it is collected

    Speech models still struggle with African languages and accents. Here is how diverse, consent-tracked speech data is recorded, transcribed and checked.

    6 October 2026 · 2 min read
  • An operator monitoring automated workflows on screenAI and data

    The human exception team behind your automation

    Why automation projects stall on exceptions, and how a human team that reviews low-confidence outputs, monitors bots and categorises failures keeps workflows moving.

    22 September 2026 · 2 min read
  • A moderator reviewing flagged content against policyAI and data

    Content moderation done right: consistency, context and moderator wellbeing

    What good content moderation looks like in practice, from policies and enforcement matrices to appeals, reporting and the safeguards that protect moderators.

    8 September 2026 · 3 min read

Want to talk it through with a specialist?

Tell us about your team and processes. We reply within one working day with a suggested team and price.

Book a free consultationChat on WhatsApp